
Why you should care right now
Imagine your e‑commerce has just integrated OSPOS, the open‑source POS I customized for the Quase Tudo store, with Mercado Livre. With each sale, inventory must be updated within milliseconds, otherwise a customer ends up buying a product that’s already out of stock and the store’s reputation plummets. In the first test, the Mercado Livre API started responding with 429 Too Many Requests errors, and at the same time the database became overloaded with repeated queries to the same product record. The solution turned out to be to place a Redis layer between the application and the database, using Redis not only as a cache but also as a rate limiter and as a queue broker.
If you’ve already faced a similar situation – or haven’t yet, but know it could happen – this article shows, step by step, how to build these three essential functions with Node.js, Docker, and just a few lines of code.
1. Preparing the environment with Docker
Starting with Redis inside a container makes it easier to replicate the environment in development, testing, and production. The command below creates a lean docker-compose.yml:
services:
  redis:
    image: redis:7-alpine
    container_name: redis-dev
    ports:
      - "6379:6379"
    restart: unless-stopped
    volumes:
      - redis-data:/data
    # A cache cannot have unlimited memory: once it runs out, Redis stops
    # answering instead of evicting. maxmemory plus an eviction policy is
    # what keeps the service up under pressure.
    command:
      - redis-server
      - --save
      - "60"
      - "1"
      - --loglevel
      - warning
      - --maxmemory
      - 256mb
      - --maxmemory-policy
      - allkeys-lru

volumes:
  redis-data:
Run docker compose up -d and Redis is ready to accept connections on the default port. In my inventory-service project I used exactly this setup to synchronize catalog and inventory between OSPOS and Mercado Libre, ensuring that latency was predictable.
Tip: keep the same image version across all environments. The
redis:7-alpineimage is the smallest and already includes the streams and Lua modules that we will use later.
2. Cache Patterns in Node.js
2.1. Quick Concepts
- Write‑through – every write to the database also updates the cache.
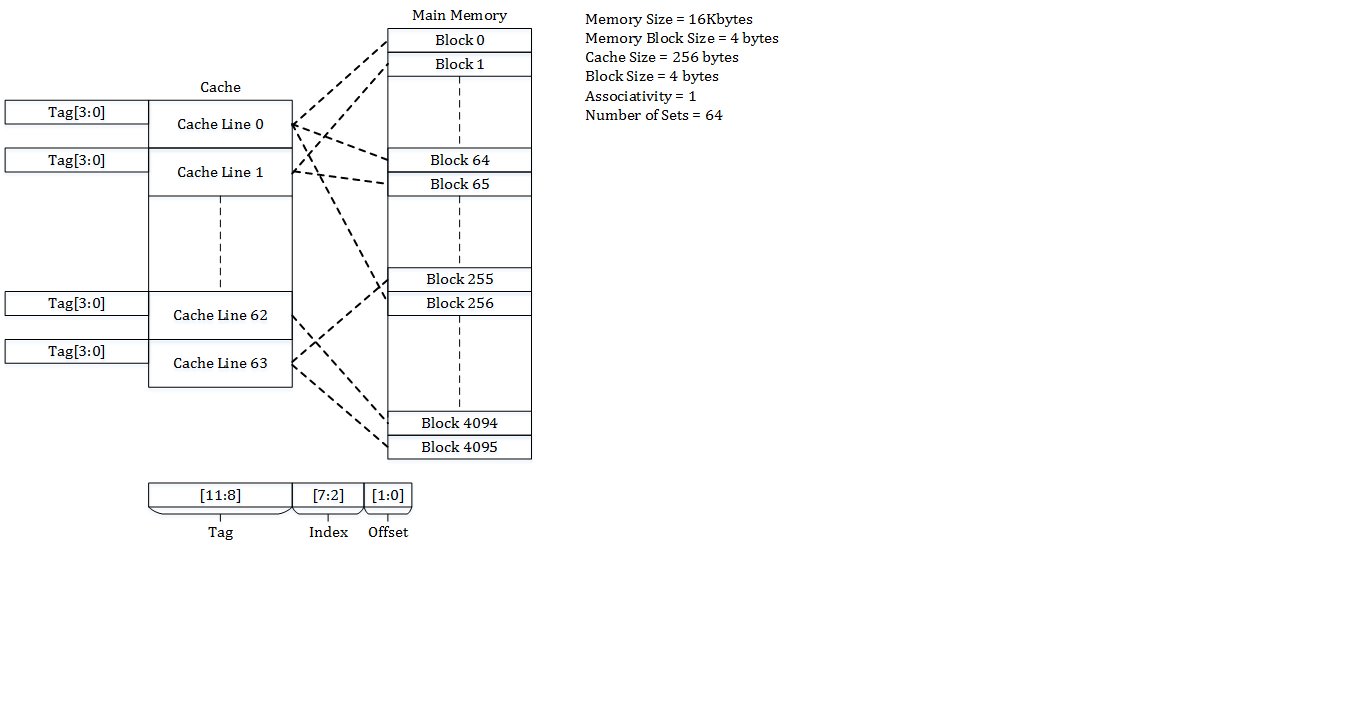
- Cache‑aside – the application reads from the cache; if the data isn’t there, it queries the database, writes to the cache, and returns it to the client.
In my day‑to‑day work, the cache‑aside pattern has been the most flexible, especially when the write load is lower than the read load, such as in inventory synchronization.
2.2. Implementing cache‑aside with redis (v4)
Install the official client:
npm i redis@4
Create a redisClient.js module:
import { createClient } from 'redis';

const client = createClient({
  url: 'redis://localhost:6379',
});

client.on('error', err => console.error('Redis error', err));

await client.connect();

export default client;
Now, an example function that fetches a product from PostgreSQL (via pg) and uses cache‑aside:
import client from './redisClient.js';
import { query } from './db.js'; // wrapper do pg

export async function getProduct(id) {
  const cacheKey = `product:${id}`;

  // tenta ler do Redis
  const cached = await client.get(cacheKey);
  if (cached) {
    return JSON.parse(cached);
  }

  // se não encontrou, busca no banco
  const { rows } = await query('SELECT * FROM products WHERE id = $1', [id]);
  const product = rows[0];

  // grava no cache por 10 minutos
  await client.setEx(cacheKey, 600, JSON.stringify(product));

  return product;
}
In the inventory-service I used exactly this logic to avoid repeated queries to the same product record when the POS requested the price to display at checkout.
2.3. Simplified Write‑through
When the application creates or updates a product, just call the same cache function:
export async function upsertProduct(product) {
  const { rows } = await query(
    `INSERT INTO products (id, name, price, stock)
     VALUES ($1, $2, $3, $4)
     ON CONFLICT (id) DO UPDATE SET
       name = EXCLUDED.name,
       price = EXCLUDED.price,
       stock = EXCLUDED.stock
     RETURNING *`,
    [product.id, product.name, product.price, product.stock]
  );

  const saved = rows[0];
  const cacheKey = `product:${saved.id}`;

  // atualiza o cache imediatamente
  await client.setEx(cacheKey, 600, JSON.stringify(saved));

  return saved;
}
Thus, the cache never becomes outdated, even if the database is altered by another process.
3. Rate limiting with sliding window
3.1. Why not just use express-rate-limit
Many projects rely on middleware that stores counters in memory. This works on a single server, but it breaks as soon as you scale to multiple instances—each node has its own count. Redis, being centralized, solves this problem.
3.2. Sliding window algorithm in Lua
The most precise algorithm for rate control is the sliding window log. It records request timestamps in a list and removes those that have already “left” the window. The Lua code below is ready to be used as a Redis script:
-- KEYS[1] = chave do usuário (ex.: "rl:12345")
-- ARGV[1] = limite de requisições (ex.: 100)
-- ARGV[2] = janela em milissegundos (ex.: 60000)

local key = KEYS[1]
local limit = tonumber(ARGV[1])
local window = tonumber(ARGV[2])
local now = redis.call("TIME")
local timestamp = now[1] * 1000 + math.floor(now[2] / 1000)

-- remove entradas antigas
redis.call("ZREMRANGEBYSCORE", key, 0, timestamp - window)

-- conta quantas ainda restam
local count = redis.call("ZCARD", key)

if count >= limit then
  return 0
else
  -- The member must be unique within the ZSET. Using the timestamp alone as
  -- the member makes two requests in the same millisecond collide: the second
  -- ZADD overwrites the first and the counter sees 1 where there were 2,
  -- which opens a hole for bursting past the limit.
  local seq = redis.call("INCR", key .. ":seq")
  redis.call("PEXPIRE", key .. ":seq", window)
  redis.call("ZADD", key, timestamp, timestamp .. "-" .. seq)
  redis.call("PEXPIRE", key, window)
  return 1
end
3.3. Integrating with Node.js
import client from './redisClient.js';
import fs from 'fs';
import path from 'path';

// carrega o script apenas uma vez
const script = await fs.promises.readFile(
  path.resolve('scripts/slidingWindow.lua'),
  'utf8'
);
const sha = await client.scriptLoad(script);

/**
 * Verifica se o IP pode fazer a requisição.
 * @param {string} ip
 * @param {number} limit
 * @param {number} windowMs
 * @returns {Promise<boolean>}
 */
export async function canProceed(ip, limit = 100, windowMs = 60_000) {
  const key = `rl:${ip}`;
  const result = await client.evalSha(
    sha,
    {
      keys: [key],
      arguments: [limit, windowMs],
    }
  );
  return result === 1;
}
And in the Express middleware:
// Trust only the hops you actually control.
app.set('trust proxy', 1);

app.use(async (req, res, next) => {
  // IMPORTANT: without this, req.ip is the proxy/load balancer's IP, not the
  // client's. The effect is the whole world landing in the same rate-limit
  // bucket: one legitimate user spending 100 requests locks everyone out.
  const ip = req.ip;
  if (await canProceed(ip)) {
    return next();
  }
  res.status(429).json({ error: 'Too many requests' });
});
In the lead-pipeline I added this limiter to prevent the lead enrichment API from being hammered by bots, keeping latency stable even under traffic spikes.
4. Queues with BullMQ
4.1. When to use queues
- Asynchronous processing of images, PDFs, or videos.
- Batch email sending.
- Integrations that depend on third‑party APIs with rate limits.
In the provider-health-daemon project I needed to orchestrate calls to multiple AI providers, respecting cooldowns. BullMQ was the natural choice because it already runs on Redis and offers advanced features like retries and rate limiting per queue.
4.2. Installing BullMQ
npm i bullmq
4.3. Creating a notification queue
import { Queue, Worker, QueueEvents } from 'bullmq';
import client from './redisClient.js';

const notificationQueue = new Queue('notifications', {
  connection: client,
});

export async function enqueueEmail(to, subject, body) {
  await notificationQueue.add('send-email', { to, subject, body }, {
    attempts: 3,
    backoff: {
      type: 'exponential',
      delay: 5000,
    },
  });
}
4.4. Consumer (worker)
const worker = new Worker(
  'notifications',
  async job => {
    if (job.name === 'send-email') {
      const { to, subject, body } = job.data;
      // aqui chamaria o serviço de e‑mail real
      console.log(`Enviando e‑mail para ${to}`);
    }
  },
  { connection: client }
);

worker.on('failed', (job, err) => {
  console.error(`Job ${job.id} falhou:`, err);
});
4.5. Observing events
const events = new QueueEvents('notifications', { connection: client });
events.on('completed', ({ jobId }) => {
  console.log(`Job ${jobId} concluído`);
});
With BullMQ I was able to decouple report generation from Plexo (task manager). Each report is placed on the queue, processed in the background, and, in the end, the user receives a Slack notification.
5. Pub/Sub for real‑time events
Redis provides a native publish/subscribe pattern, useful for lightweight notifications or for synchronizing state across instances. A typical retail scenario is notifying the front‑end that a product’s stock has changed.
5.1. Publishing an event
export async function publishStockChange(productId, newStock) {
  const channel = `stock:${productId}`;
  await client.publish(channel, JSON.stringify({ productId, newStock }));
}
5.2. Consuming in another process
const subscriber = client.duplicate();
await subscriber.connect();

await subscriber.subscribe('stock:*', (message, channel) => {
  const data = JSON.parse(message);
  console.log(`Estoque atualizado: ${data.productId} → ${data.newStock}`);
  // here you could invalidate the cache or update the UI via WebSocket
});
In inventory-service I used exactly this flow so that the React frontend was updated instantly when stock was changed by a POS sale.
6. Production: clustered mode
In production environments, a standalone Redis can become a single point of failure. Cluster mode distributes key slots across multiple nodes, enabling horizontal scalability.
It is worth being precise about what it delivers, because it is easy to over-promise here: cluster on its own does not give fault tolerance. What it gives is slot distribution and the ability to grow horizontally. Fault tolerance comes from a different feature, replicas, and the example below uses --cluster-replicas 0 precisely because it is the simplest to set up locally. With zero replicas, if one of the three nodes dies, its slots become unavailable — there is no copy to fail over to.
When you actually want to survive losing a node:
# 3 masters + 1 replica each = 6 nodes, every master with a copy
docker exec -it redis-node-1 redis-cli --cluster create \
  172.28.0.11:7000 172.28.0.12:7001 172.28.0.13:7002 \
  172.28.0.14:7003 172.28.0.15:7004 172.28.0.16:7005 \
  --cluster-replicas 1
Two caveats that only show up once you are in production:
--cluster-replicas 1needs at least 6 nodes. Redis refuses to create the cluster without enough nodes to distribute masters and replicas.- Replication is asynchronous. A replica can lag behind its master when the failure hits, and you lose the writes that never made it across. For a cache that is usually fine. For a BullMQ queue, weigh it more carefully: a job acknowledged but not replicated is a job lost.
6.1. Setting up a local cluster with Docker Compose
services:
  redis-node-1:
    image: redis:7-alpine
    command: ["redis-server", "--cluster-enabled", "yes", "--cluster-config-file", "nodes.conf", "--port", "7000"]
    ports: ["7000:7000"]
    volumes:
      - node1-data:/data
    networks:
      redis-net:
        ipv4_address: 172.28.0.11

  redis-node-2:
    image: redis:7-alpine
    command: ["redis-server", "--cluster-enabled", "yes", "--cluster-config-file", "nodes.conf", "--port", "7001"]
    ports: ["7001:7001"]
    volumes:
      - node2-data:/data
    networks:
      redis-net:
        ipv4_address: 172.28.0.12

  redis-node-3:
    image: redis:7-alpine
    command: ["redis-server", "--cluster-enabled", "yes", "--cluster-config-file", "nodes.conf", "--port", "7002"]
    ports: ["7002:7002"]
    volumes:
      - node3-data:/data
    networks:
      redis-net:
        ipv4_address: 172.28.0.13

networks:
  redis-net:
    driver: bridge
    ipam:
      config:
        - subnet: 172.28.0.0/16

volumes:
  node1-data:
  node2-data:
  node3-data:
After bringing up the containers, create the cluster:
docker exec -it redis-node-1 redis-cli --cluster create \
  172.28.0.11:7000 172.28.0.12:7001 172.28.0.13:7002 \
  --cluster-replicas 0
Look at the networks block above. redis-cli --cluster create needs fixed addresses, and Compose does not provide them on its own: the Docker subnet is assigned dynamically and changes from machine to machine. Without the explicit ipv4_address, the command works on your machine and fails on your colleague's — which is the definition of "works on my machine".
6.2. Connecting a Node.js client to the cluster
import { createCluster } from 'redis';

const cluster = createCluster({
  rootNodes: [
    { url: 'redis://localhost:7000' },
    { url: 'redis://localhost:7001' },
    { url: 'redis://localhost:7002' },
  ],
});

await cluster.connect();

export default cluster;
From that point on, all cache calls, rate limiting, and queues operate transparently, as the client routes each key to the appropriate node.
7. Conclusion
Implementing caching, rate limiting, and queues with Redis is not just “big‑company stuff”. In projects like inventory-service or lead-pipeline I was able to cut query latency by up to 70 %, avoid blocks due to API limits, and ensure that critical tasks were processed even when the primary server faced load spikes.
The combination of Docker, the official redis client, and libraries such as BullMQ provides a fast and reliable path.
Next steps
What this post builds is already fine for low-traffic production. The known gaps, in the order I would face them:
- Cache stampede — cache-aside has a race: when a key expires, every simultaneous request falls through to the database at once.
ttl-lru(needs Redis >= 6.2) fixes it with a stampede lock, or the simple pattern of guarding the rebuild per key. Measure before optimizing: the symptom is latency under spike, not errors. - Invalidation — the 10-minute TTL in the example is a guess. When data changes by event (the inventory flow in this post), the right move is to invalidate on write, and the Pub/Sub from section 5 is the natural hook.
- Truly distributed rate limiting — the Lua script assumes a single Redis. With a cluster, the key has to land in a single slot (use hashtags
{user123}, otherwise theZADDandZREMRANGEBYSCOREon different nodes break the algorithm). - Observability —
SLOWLOG GET,INFO memoryandLATENCY DOCTORtell you why Redis got slow before you guess. - Auth and TLS — the local compose exposes port 6379 on the host with no password. In any shared environment,
requirepassplusredis://:password@hostare not optional.
Beyond Redis: rate limiting on a real network needs a key per user rather than per IP, otherwise an entire NAT (an office, a school, a carrier) shares one bucket.
Post glossary
- api
- Application Programming Interface: a set of rules that lets one program talk to another, exposing data and features in a standardized way.
- redis
- An in-memory data store used as a cache, queue and message broker, with extremely low latency.
- cache
- Temporary storage of already-computed or fetched data to speed up future access and reduce server load.
- node
- Node.js: a JavaScript runtime outside the browser, built on the V8 engine, used mainly for servers and command-line tools.
- postgresql
- Advanced open source relational database known for extensibility, native JSON support and ACID compliance.
- middleware
- A function that intercepts requests on a server to run logic before or after the handler, such as auth and logging.
- event
- A relevant system occurrence (click, order, message) that triggers asynchronous actions, the basis of event-driven architectures.
- react
- A JavaScript library for building user interfaces from reusable components, maintained by Meta.
- replica
- A copy of a database or service kept on another node to increase availability and spread reads.
- github
- Source code hosting platform with Git version control, used for collaboration and project deployment.